Complete metrics, latency measurements, failure categorization, and visual evidence across all 10 evaluated language fixtures.
OCR Benchmark Results & Error Taxonomy?
Full results from the official September 20, 2026 test execution on Node.js v22 with Tesseract.js 5.1.1 (LSTM OEM 1, PSM 6). * Scripts without space word boundaries (Chinese, Japanese, Hindi, Arabic) report CER and exact key-field accuracy. WER is only evaluated for space-delimited Latin and Hangul scripts.
Last updated
Complete Engine Benchmark Scorecard
Full results from the official September 20, 2026 test execution on Node.js v22 with Tesseract.js 5.1.1 (LSTM OEM 1, PSM 6).
10-Language Benchmark Metric Breakdown
Language / Fixture
Pack
CER
WER
Key Fields
Numeric Exact
Email Exact
URL Exact
Verdict
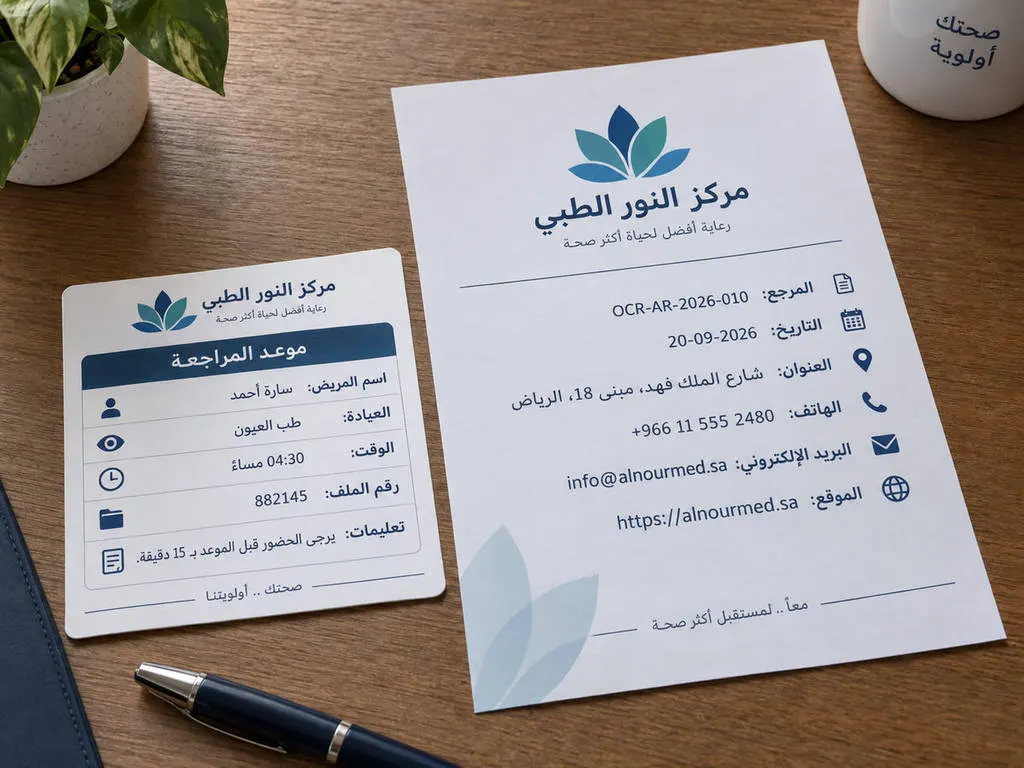
العربية OCR-AR-2026-010
ara
0.638
—*
0%(0/11)
0%
0%
0%
FAIL
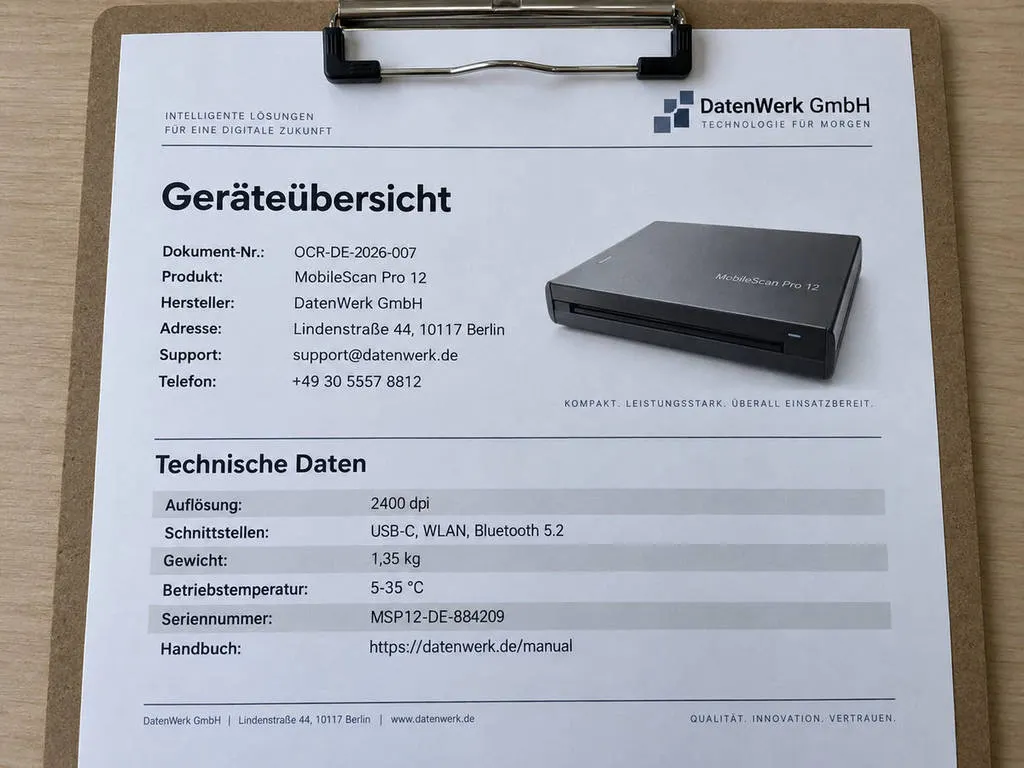
Deutsch OCR-DE-2026-007
deu
0.302
0.738
100%(11/11)
100%
100%
100%
PASS
English OCR-EN-2026-001
eng
0.178
0.265
93.8%(15/16)
100%
100%
100%
WARN
Español OCR-ES-2026-005
spa
0.527
1.200
62.5%(10/16)
58.3%
0%
100%
FAIL
Français OCR-FR-2026-006
fra
0.402
0.809
83.3%(10/12)
87.5%
100%
100%
FAIL
हिन्दी OCR-HI-2026-009
hin
0.607
—*
22.2%(2/9)
20%
0%
0%
FAIL
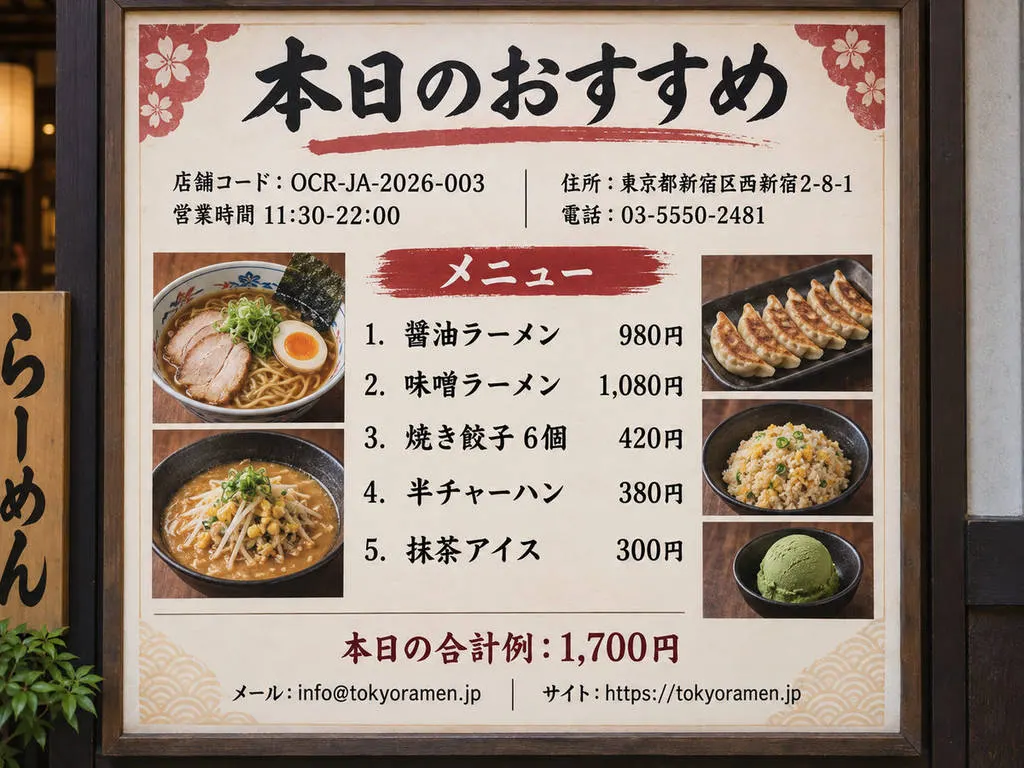
日本語 OCR-JA-2026-003
jpn
0.667
—*
27.8%(5/18)
33.3%
100%
100%
FAIL
한국어 OCR-KO-2026-004
kor
0.627
0.860
63.6%(7/11)
85.7%
0%
0%
FAIL
Português OCR-PTBR-2026-008
por
0.431
0.900
70%(7/10)
83.3%
0%
100%
FAIL
简体中文 OCR-ZH-2026-002
chi_sim
0.668
—*
18.2%(2/11)
40%
0%
0%
FAIL
* Scripts without space word boundaries (Chinese, Japanese, Hindi, Arabic) report CER and exact key-field accuracy. WER is only evaluated for space-delimited Latin and Hangul scripts.
Where Browser OCR Struggles: Failure Taxonomy
High-contrast digital scans perform adequately in browser WebAssembly OCR. However, real-world creator and photo workflows present systematic failure modes:
Category 1
CJK Inter-character Spacing & Segmentation
Observed in: Simplified Chinese (OCR-ZH-2026-002, 18.2% key fields) and Japanese (OCR-JA-2026-003, 27.8% key fields).
The underlying Tesseract LSTM engine inserts ASCII spaces between contiguous Han and Kana glyphs (e.g. outputting 社区 服务 中 心 instead of 社区服务中心). This degrades exact substring searches and form autofill. While space-stripping helps diagnostics, character substitutions (such as confusing '二' with '三' or '醤油' with '普油') remain prevalent in natural lighting.
Category 2
Non-Latin Scripts & Complex Shapers
Observed in: Arabic (OCR-AR-2026-010, 0% key fields) and Hindi (OCR-HI-2026-009, 22.2% key fields).
Arabic cursive joining rules and Devanagari vertical conjuncts fail on scene-photographed text. On our Arabic clinic fixture, zero of 11 scored fields matched; cursive headlines collapsed into disconnected glyph fragments. On Hindi notices, Latin phone numbers survived but the Devanagari headline was entirely lost.
Category 3
Photographic Noise & Graphic Elements
Observed in: Japanese ramen menu (OCR-JA-2026-003) and English desk invoice (OCR-EN-2026-001).
Without dedicated layout segmentation or picture masking, the OCR engine treats high-contrast texture in photographs as typography. High-resolution photos of food were transcribed into ghost kanji strings (such as 隊暫要衣 and ワニ). Similarly, decorative desk items (mugs, foliage) generated garbage text tokens around the borders.
Thermal receipt paper creases cause horizontal character slicing. Single-digit drops were observed in price columns: 2,85 € had the digit 5 dropped and the Euro sign misread as a cent mark (2,8¢). The tax summary line was completely lost, though overall document totals survived.
Category 5
Stylized Display Headers & Sizing Variance
Observed in: English office invoice (OCR-EN-2026-001, 93.8% key fields, WARN).
Tesseract is tuned for uniform body text. When documents feature heavy, oversized display titles (such as a 48pt bold 'INVOICE' header), the character strokes exceed the LSTM line segmenter's expected aspect ratio and are ignored, even while 8pt table items directly below are read with 100% precision.
Complete Fixture Evidence Archive
Examine the original rendered photograph, ground truth excerpt, recognized OCR output, and exact error notes for every fixture in the benchmark suite.
OCR-AR-2026-010ArabicClinic information sheet and appointment card
pack: araFAIL
Fixture OCR-AR-2026-010 · Controlled scene
Key Field Accuracy0%
CER (Error Rate)0.638
Expected Ground Truth (sample)
مركز النور الطبي
المرجع: OCR-AR-2026-010
التاريخ: 20-09-2026
العنوان: شارع الملك فهد، مبنى 18، الرياض
الهاتف: +966 11 555 2480